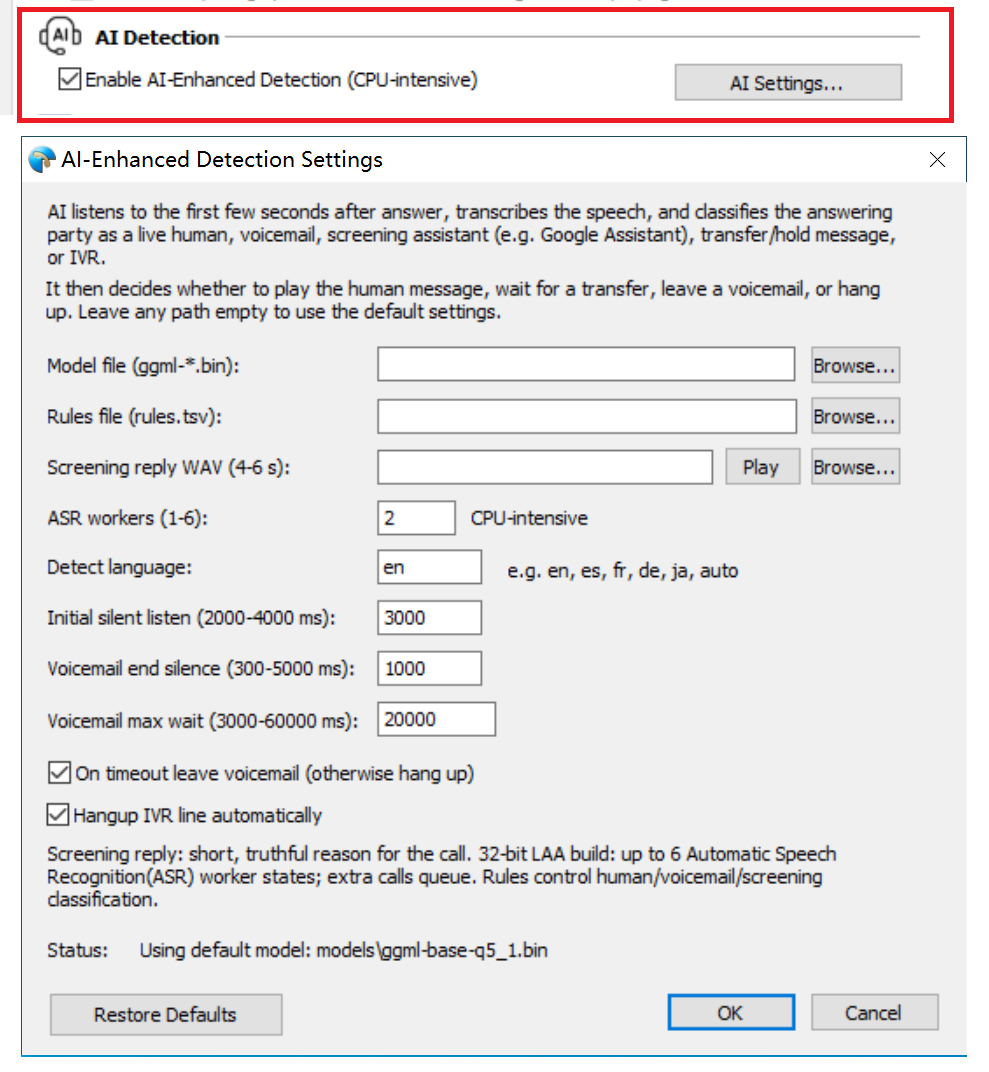
Ecsow’s AI-Enhanced Detection comes with a lightweight English speech model built-in. This is why the model fields may be left empty on a fresh installation.
We also offer free downloadable models for five other languages: Spanish, Arabic, Mandarin Chinese, Japanese, Korean and Vietnamese.
The whole setup only has four simple steps: download the model file, extract it, select the model folder inside AI settings, then restart Ecsow. Most of the waiting time is for the file download, and the process usually takes around 10 minutes.
You only need to install an extra language model if you are handling non‑English calls. If you haven’t turned on AI detection yet, please check our introductory setup guide first.
Step 1: Download the model
Go to the Ecsow download page and find the AI detection models. Six languages are listed.
Each link is a .tar.bz2 file. The “base” models hear more accurately than the “tiny” ones and use more CPU. Pick the language you actually call in — the model only understands one language at a time.
Step 2: Extract the archive to a local folder
ou can use 7‑Zip or Windows’ built‑in extraction tool. .tar.bz2 requires two extraction steps: first unpack the .bz2 file, then extract the .tar file inside it.
Place the extracted files in a simple path, for example: C:\EcsowModels\moonshine-base-es
Tip: Use a short folder path without spaces. This helps avoid loading errors.
Now check the folder. It must contain these three files:
encoder_model.ortdecoder_model_merged.orttokens.txt
If any file is missing, you may have opened the outer archive folder. Go deeper into the extracted directory and check again.
Step 3: Point Ecsow to the model folder
Open Tools > Options > Voice Activity Detection and click AI Settings. This is the panel you should see.
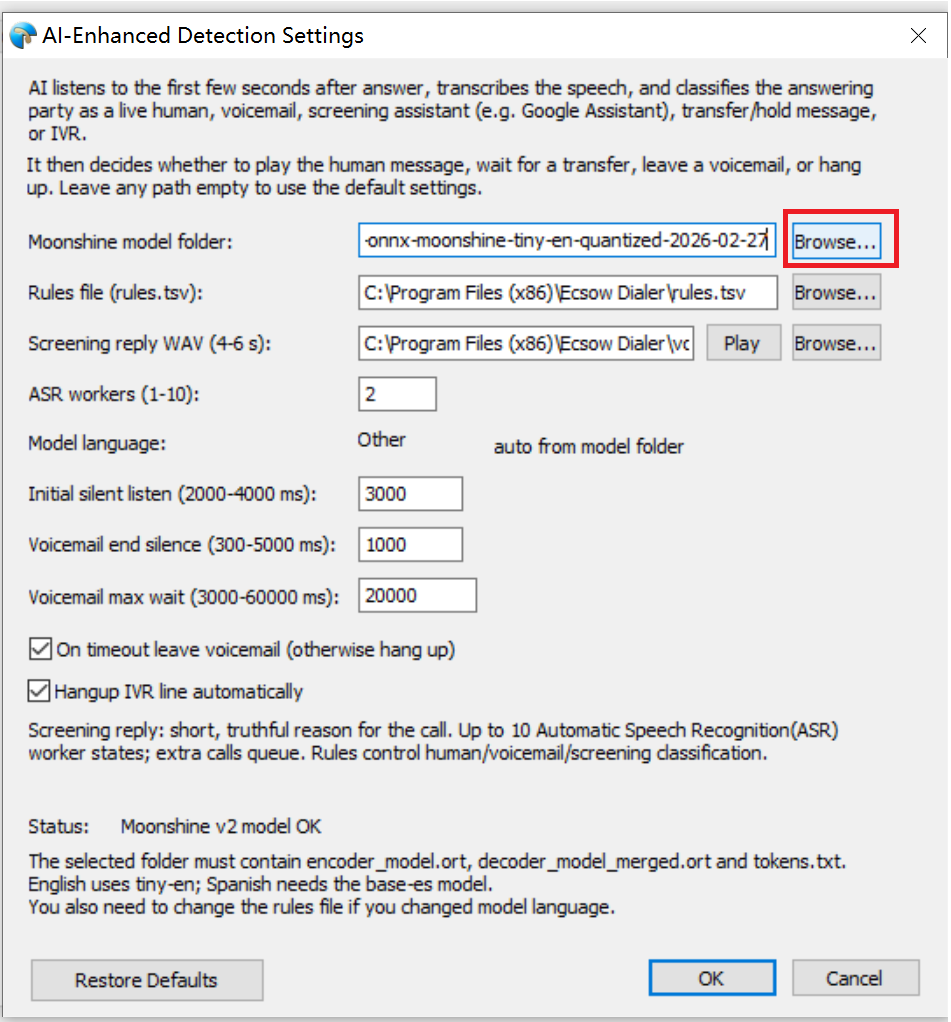
Find the setting labelled Moonshine model folder, click Browse, and select the folder you extracted in Step 2.
Ecsow will validate the folder automatically once selected. If you see Moonshine v2 model OK in the status bar at the bottom, the model loads correctly. Save your settings.
You do not need to manually select the language; Ecsow detects it automatically from the model files.
Step 4: Match the rules file to the language
After switching to a new language model, you must use the corresponding rules.tsv file.
The rules file (rules.tsv) is what turns transcribed speech into a decision — person, voicemail, screening assistant, phone menu. The default one matches the English model.
If you point the model at Spanish and leave the English rules in place, the two disagree. The model hears Spanish, the rules expect English, and the classification stops being trustworthy.
So when you change the model, change the rules file to match. Not sure which file fits your language? Ask support before you go live with it. It is a one-line fix once you have the right file.
Step 5: Save settings and restart Ecsow
Click OK, then close and restart Ecsow. The new model loads at startup, so a restart is what makes it take effect.
After the restart, the same status line you saw in step 3 is your confirmation. Then make a short test call and check the detection behaves the way the setup guide describes.
When something looks wrong
| Symptom | Likely cause |
|---|---|
| Status line does not say “model OK” | Wrong folder, or one of the three files is missing. Recheck step 2. |
| Detections make no sense in the new language | The rules file was not changed. Recheck step 4. |
| The machine got slower on busy hours | A base model costs more CPU than tiny. Watch the task manager during your busiest hour, and lower ASR workers if calls start queuing. |
None of these need a reinstall. Undo the field, restart, and the default English model comes back.
Quick answers
Do I need any of this for English calls?
No. The English model ships inside the installer. Leave the model field empty and it works.
Where do the model files come from?
The links on the download page point to the public release page of the sherpa-onnx speech project, which builds the Moonshine models Ecsow uses. Nothing is repackaged or resold.
Does the model send my audio anywhere?
No. The speech model runs on the machine running Ecsow. Nothing is uploaded and there is no per-minute charge, whichever model you use.
Which editions can load a custom model?
Both. Ecsow Auto Dialer and Ecsow Voice Broadcast share the same settings panel and the same model folder field.
Should I pick the tiny or the base model?
If both exist for your language, tiny is lighter on CPU and base is more accurate. On an older machine with many lines, start with tiny. If your CPU sits mostly idle while calling, move up to base.